Wednesday, January 13, 2016

VascoEtruscan and IndoUralic - and their relation to MesoEuropean

For my MesoEuropean speculation, I'm trying to hammer out a type of "jargon" that would include Uralic, IndoEuropean, Etruscan, and Basque. While I don't think they're directly related, there are parallels between these that can be observed with closer inspection; though the problem of testability arises when you compare any two of these individually.

I've tried conquering this problem with subgrouping Uralic with IndoEuropean as a genetic entity, and Etruscan and Basque as a possible one, though it helps, it certainly doesn't fix the problem. The problem being any "cognate" forms may originate from none of these language families specifically, but may be present in all of them. Further, these "cognate" (really bad word for it) need not genetically be related to one another, but could have arisen areally.

For instance, haber and have in Spanish and English, used almost identically, but not technically cognate. Their similarity may or may not have influenced or influence the developement of either, but that doesn't change the fact that those communicating between these languages will tend to use a form "have" to translate "haber", even if the corresponding Germanic form of "haber" were to be used as well.

This creates an obvious testability problem to add to the already existing ones. Now, not only can't we distinguish what is loaned and what isn't (a problem even extending to both "subdivisions"), we can't even be sure what forms are really convergent by this (as I'm pretty sure haber and have developed ...)

An example of these likely common borrowings/convergences being:

A pronominal system with a specific type of vowel gradation holding specified meaning:
mu(n)/mo(n), mi(n)/me(n), ma(n)/mə(n)/m∅(n) - 1st Person
tsu(n)/tso(n), tsi(n)/tse(n), tsa(n)/tsə(n)/ts∅(n) - 2nd Person
su(n)/so(n), si(n)/se(n), sa(n)/sə(n)/s∅(n) - 3rd Indefinite/Human
tu(n)/to(n), ti(n)/te(n), ta(n)/tə(n)/t∅(n) - 3rd Person Definite

*/ts/ used because I didn't want to give the impression that both could be reconstructed at any branch, as it really does matter which you choose. With the only exception being IndoEuropean, which shows /s/ on verbs and /t/ in pronouns for the 2nd person, and the 3rd person forms show seperate roots for /s/ and /t/ in differing branches such as Uralic (assuming any validity to the speculation). For the 2nd person, Uralic shows /t/, like with Luwian, also an /ri/ developing from that /ti/ form. Though the 2nd person and 3rd person forms in IndoEuropean and Uralic "seem related", I can get to why, possibly some "thou, this" distinction that can be later explored.
Both "thou" and "this" correspond to the Basque "hi" and "hau" respectively. In the above, that would be ts > z /s/, and t > h.
Etruscan would show the same /z/ and /h/ developements as Basque in this framework.
Correction made: I confused the Basque singular "thou" hi with the plural zu. This does get rid of the association between /u/ and /i/ and number.Also ni "I" and gu "we" below.

*-(n) should be more accurately rendered -n, and is obligatory in PUralic it would seem, but optional (?) in PIndoEuropean, or at least both forms with and without it can be seen in the possessive forms. This has lead to the moi- moin- distinctions, maybe? Though it may have been dropped too, and have been originally necessary, this is unclear. Though both exist in Uralic and IndoEuropean, without the -n element, Uralic has it in its enclitic forms (which are nearly identical to their IndoEuropean counterparts). Not sure what the Basque and Etruscan would yield. Though I know that Basque lacks the final nasal. It appears like it may just differentiate pronominal and attributive forms, if this nasal ending is even to be differentiated at all from the base root (hence the parenthesis). As a very simple sound change could eliminate it from suffixes.
The very nature of a root without the -n appears like it could be problematic for both Uralic and IndoEuropean, despite being reconstructible for both.

*3rd Person definite forms are historically related both back to the plural suffixes and the demonstrative pronouns with definite meaning under this model.
Some have linked the PIE plural -s with the PU -t, but my own thinking is that these are somewhat seperate. The reason for this, is simplicity. Both s- and t- exist as indefinite and definite forms of demonstrative roots, and assuming its an enclitic demonstrative root in origin (easily reconstructed and uncontroversially as -es in PIE and -t in PU), and their parallel t- (deictic demonstratives in both, and technically all 4; often the reflexive pronoun in Uralic) and s- (IE 3rd Reflexive and PU 3rd Person pronoun).

Also, evidence from IndoEuropean using a collective ending for Neuter nouns and pronouns seems to suggest that these originally didn't decline for number in the singular ~ dual ~ plural like Human/Animate nouns originally did (Masculine by the time of PIE), rather, by an Individual vs. collective type distinction.
This gives us a clear PIE neuter singular demonstrative -d as cognate with the PU -t. Though these would have necessarily developed seperately. I'm going to come back to the reason why in the section on ablaut.

You can see the mess this would create, trying to resolve this as one common root, instead of a merger of two seperate roots into a suppletive type pronoun in either branch independantly developing, IndoEuropean or Uralic.

The ∅-grade and a-grade forms might possibly be seperate or they may not be. Their meaning seems to not necessarily have been distinguished in personal pronouns, but for demonstratives they lend a sort of general/distal deixis (giving a generalized meaning "that").

The i/e-grade form has two seperate usages, it would seem.
In demonstrative pronouns, this grade gave rise to the "near deixis", and is constructed the same way in PIE as that plural suggestion, and indeed -i- for near deixis in PU. Further, this form may actually be related to the PIE root "this" also beginning with j-, and the root kj- "this".
In some branches of IndoEuropean, this remained the plural ending, alternating with the plural -es in other branches. In yet other branches, the j- root actually gave rise to the definite declension such as with Lithuanian and Latvian, (as t- had done in Balkan Romance, Luwian, as well as Bulgarian and Macedonian). Curiously, Germanic shows -n- for that same definite declension (so-called weak stems), seemingly related to the word "a/an/one".

While the definite meaning clearly developed seperately, there seems to have been some construction similar to what we see in Basque as the original state for IndoEuropean. Whether or not the noun was always declined for case in these constructions, the following determiner became declined for case, gender and number. This easily explains the independant developements of these as independant case endings for the Indefinite and Definite declensions in some branches, but there is a controversial element to it. It may well get rid of some case endings.....
.... I'll get to that later, this has gotten way too long as it is, we'll deal simply with phonological issues for now.

While it doesn't seem related (for the most part), Sumerian also seems to have a similar system of Ablaut for its pronouns. It may not be related. Though a comparison can be drawn between Sumerian and IndoEuropean enclitic personal pronouns:
o/u-grade IndoEuropean and Sumerian genitive/possessive enclitics
e/i-grade IndoEuropean Oblique and Sumerian Ergative enclitics
a-grade If the same as zero-grade, this would be the equivalent of the root-form in Basque, IndoEuropean, and Sumerian.

Monday, December 14, 2015

Dative Plural -mos in Luwian?

For the article:
A Brief Introduction to Hieroglyphic Luwian


I noticed their enclitic 3rd Person Dative Plural pronoun was -mans, and couldn't help but notice a similarity to the Dative Plural -manza.

In Hittite the Nom.-Acc. Singular for this is -at, and plural is -ata. The Slavic variant of this (yes, they have the same enclitic) is Dative Singular mu. Basically, the same endings that often form case endings, are also enclitic pronouns when it comes to the Dative and several others in Slavic, with the Luwian evidence, we can see that clearly the -mi(s)/-mus and -bis/b(j)os distinction seems to arise from earlier enclitic suffixation.

I don't think the forms are identical -manza and -mus/-mi(s), but they're definitely appearing to be related. What do you think?

Wednesday, December 2, 2015

IndoUralic - Problems, Solutions and Unresolved Issues Part one - Phonological Issues

The problem with the IndoUralic hypothesis, isn't one of a lack of cognates, nor of a lack of strong correlations. It's one of a small reconstructible ProtoUralic grammar and lexicon, that has its entire history of being right side by side with IndoEuropean. The reason this is a problem is obvious, it means that the two language families have had almost (if not more than) 5,000 years to influence eachother. To those less familiar with either language family, that's the entire history of potentially both families.

From a geographical standpoint, both have their origins in the Volga-Kama river system, specifically originating in the area around the Middle Volga river area. For the ProtoUralic speakers, the Kama river and lower Ural mountains area, and for ProtoIndoEuropean with the expansion of the Yamna Cultural complex (to be specific, the spread of horse domestication), from the Middle Volga river part of the Pontic-Caspian Steppes.

The good news is, the earliest loanwords appear to be predictible. Then again, maybe not. For instance, we have loanwords in ProtoUralic from ProtoIndoEuropean itself (presumably), or an immediate descendant. They appear to be late PIE loans, but who knows? We know that they are loans though:

Early PIE nom (Nom.) ~ nomen (Obl.) "name" > PUralic nime (from the Obl./Indirect form)
Early PIE wodr (Nom.) ~ uden/weden (Obl.) "water" > PUralic weti (from the Obl./Indirect form)

*Source of PUralic reconstructed forms: The Horse, the Wheel, and Language - by David W. Anthony
*The difference between the a-dialects and the o-dialects, isn't so much one of ancestry, as it is a phonological rule that o>a (/o/ becomes /a/), which may or may not really go back to Late PIE, but is present in Hittite as far as we can tell, so it is assumed that this change would have been present at that state.


It's safe to conclude also, that ProtoUralic isn't an IndoEuropean language, so its not descended from PIE, so anything not traceable to either PIE or its daughter languages, may potentially be cognate at an earlier stage. The problem is, alot is covered in the form of earlier stages.

It may well be that all the similarities are traceable to those 5,000 years of contact, but this is a hypothesis to explore.

Thursday, November 12, 2015

The War on Wikipedia

Now, obviously, Wikipedia is no primary source of information if you want to do research on any subject; but it makes for a decent place to begin. Whatever be the quality of their sources, people who contribute do also contribute their sources to those entries found there.

Sure... there's something to be said about unqualified people posting there. Not to mention trolls and even high school teachers (yes... I knew one that bragged about trashing wikipedia to get kids not to use it....), posting nonsense to sabotage the good efforts of others. Either way, it doesn't matter, because if you look further, it works. Any mistakes can be corrected.

Though there's something else lurking behind the distrust of crowdsourced information, a distrust of those not in a position of authority. This is kinda way off topic, but its something I've noticed that came from a criticism of my earlier work using wikipedia as a starting point.

Sunday, July 12, 2015

What if PIndoEuropean Had Distinct Clusivity Pronouns?

What if ProtoIndoEuropean, or PreProtoIndoEuropean, had seperate pronouns for Inclusive and Exclusive 1st Person, dual and plural, personal pronouns?

If we were to lay out some of the reconstructions, for our example we'll use some enclitic pronouns from the Northwestern IndoEuropean branch for Illustration, it might look like this:
Potential Reconstruction of an Earlier System (Reconstruction and Hypothesis mine).


Proto- Germanic
Common Baltic
Common Slavic
Western IndoEuropean
1st Sing.
Nom.


já
ja
Acc.


men
mę
men
Gen.
mī

mě
mē
Poss.
mȳ

moj
moi
Dat.
mē
mi
mi
mi
1st Incl.
Dual
Nom.
wi
vě
vě
wē
Acc.


vū
wy
wū
Gen.


Poss.


Dat.


wa
wa
1st Excl.
Dual
Nom.


nē
Acc.


ny
nū
Gen.


Poss.


Dat.


na
na
1st Incl.
Plur.
Nom.


wos
Acc.


wes
Gen.


Poss.


Dat.


1st Excl.
Plur.
Nom.


nos
Acc.


nes
Gen.


Poss.


Dat.


nas
2nd Sing.
Nom.
þū
tū
ty
tū
Acc.


ten
tę
ten
Gen.
þī


tě
tē
Poss.
þȳ


toj
toi
Dat.
þē
ti
ti
ti
2nd Dual
Nom.
ġi


jē
Acc.


jū


jū
Gen.


Poss.


Dat.


ja
2nd Plur.
Nom.


jos
Acc.


jes
Gen.


Poss.


Dat.


jas
3rd Sing.
Nom.


sy
sū
Acc.


sen
sę
sen
Gen.
sī


sě
sē
Poss.
se
si
si
soi
Dat.


si
3rd Dual
Nom.


sē
Acc.


sy
sū
Gen.


Poss.


Dat.


sa
sa
3rd Plur.
Nom.


sē
Acc.


sy
sū
Gen.


Poss.


Dat.


sa
sa
*At least in some cases, ū is actually reconstructed as ō in Northwest IndoEuropean, but this distinction isn't such that it would have an impact upon the correlations noted above. (And in the case of my own speculative chart specifically, nearly all of them are reconstructible as /ō/)
*plural forms jos reconstructible as jūs/jōs; And may well derive from an adjectival form of this pronoun. Adjectival forms has -w- between the root and the vowel ending.


Any thoughts? Opposing? In favor? Uncertain?

Tuesday, June 30, 2015

ProtoIndoEuropean Dative Element -o

Accusative>Lative, Instrumental>Ablative


Accusative-Dative
Instrumental-Ablative
Sing.
Du.
Plur.
Sing.
Du.
Plur.
No Lative Element Acc-Ins
-m
-meh
-ns (<ms)
-bhi
-bhih
-bhis
Lative Element -o Lat-Abl
-mo
-ei
-moh
-mos
-bio
-bioh
-bhios
*Note: -ei would have been derived from the Locative form, and the -e- element may not have been -o- for whatever reason. Anatolian evidence, especially with regards to Hittite, is that the dative and locative endings were the same, though they had -a for the Allative (which may have been the origin of the Dative case elsewhere).
For Hittites Allative -a, its hard to tell whether or not this represents an -he element or an -o element, as it underwent the o>a shift. At least as far as we can tell from its transcription into cuneiform.
Hittite also as:
Ablative -az (-ats)
Instrumental -it

It's hard for me to say the origin of the Ablative ending, though its definitely not from the Genitive -as ending. The /ts/ element is often a result of ti>ts, like in -anti>-anza. Not sure if this is the result of the same change or not.

*Note: Accusative dual forms merged with Nominative dual forms, this may have always been this way; though the above postulation for a seperate accusative dual form is based on the dative dual forms, and is entirely speculation. As is the Ablative dual/plural forms (though Instrumental singular -mi forms are attested from Baltic and Slavic evidence).

Saturday, June 20, 2015

I've moved around Baltic, Slavic, Germanic, and Italic

I've redone some of how my site is organized, and subcategorized Baltic, Slavic, Germanic, Italic, and Celtic under Northwestern IndoEuropean.

Natlangs Old and Young: Northwestern IndoEuropean

Friday, May 29, 2015

The underrated significance of smaller dialects

As you already well know, all languages either have or will have lesser dialects. Dialectical differentiation is a part of the evolution of languages, always has been, and always will be. It just is.

To make things even better for the historical linguist, all languages today are descended from prior dialects of previous languages, sometimes several dialects at a time. Sometimes, two languages may "combine" to form a new language. We can discuss creoles and pigins another day....

In the earlier history of english, there were many instances where Old English dialects contributed different things to what became Middle English, and on from dialects of Middle English into Modern. Just as an example. Sometimes, two dialects can produce different outcomes, and sometimes both outcomes will survive in a common dialect. Like is with the pronunciation of "bury" after the vowel shifts.

It's kinda a perfect example, though not really, since by now the different pronunciations are still so similar that most don't even notice it. Though they may also only sound similar to my english ears, because differentiating vowels in this highly intercommunicative language can be difficult, when one is so familiar with different dialects that one may be suprised that some are even mutually intelligible still!

Anyway, back to "bury".....

It's pronounced either /bəɻi/ or /bɛːɻi/.

From what I've read on the internet, take it for true or not, most dialects originally had these pronunciations as seperate outcomes based on soundlaws that occurred towards the end of Middle English. One of the two would have become the outcome in London-type english, and the other Southern English; But both wound up in London English due to them just liking the way it was pronounced in the south more.

Though where I'm from, its basically pronounced either way, there is no difference between the two as they're pretty much interchangeable. Though bəɻi tends to be used more in the past tense and bɛːɻi in the present or future tense. I'm not sure if this is common elsewhere, as I haven't really seen it described anywhere, but definitely seems to be a holdout from the old english ablaut (though may very well not be).

I've noticed that at times, small inconsistencies in reconstructing earlier types of sound changes may lead to the declaration that we either:

1) Can't reconstruct a sound accurately on the basis of said small sound change descrepancies
2) Need to invoke new phonemes that should have existed on the basis of those descrepancies
3) Need to declare that all languages evolved from Lithuanian, Vedic, Aryan, Insert-Language, etc....

Okay, so the third was kind of a joke....

Though descrepancies tend to be the rule, not the exception. Not all dialects of a language survive themselves, though sometimes they'll leave behind traces of themselves in cousin-languages. These traces may then be found by a historical linguist being unable to reconstruct a form in a historical language, because it violates the rules, sometimes very much so.


Wednesday, May 6, 2015

West Slavic Project

Procrastination.... my worst enemy. My own fault being that I started with a family I'm unfamiliar with prior to present, but at least there's more familiarity now than there was. It doesn't help that the new laptop doesn't have the proper fonts, and I'm weary about downloads, nor that my word processor keeps crashing so I've basically left things on the backburner.

Maybe I need a break from my work. My notebooks are full, I lack any kind of real excuse for my lack of progress. Just that I don't want to have to deal with the problems. Guess that's where things stand. Trying to find a different approach, maybe set a schedule and limit distractions.

My worst enemy is my own attention span.

Pronominal, Case, and Verbal Similarities between unrelated languages

It's funny how similar unrelated languages can be. It seems like, as much as there are mechanisms in place to drive languages apart with time, there's also mechanisms in place to bring them closer together. The more different groups communicate, the more similar their languages become (while at the same time distinct from how they used to be).

My instinct is to question how some apparently unrelated systems can come to mirror eachother nearly identically. Do entire pronominal systems, or even nominal declension systems get borrowed from one language to another? One look at Northeast Caucasian, and right away you'll see a system very similar to that of the IndoEuropean languages, but also the Uralic languages. Or maybe they developed independantly, can we know?

Go to the americas, and nearly the entirety of the two continents' languages have deeply embedded similarities. Some say there are 3 main groupings, but most of the "amerind" languages seem quite similar to the EskimoAluet and often the NaDene languages if analyzed in the same way individual Amerind languages were analyzed.

Are languages and their systems really that unanalyzeable and unreconstructible at vast time distances? What if there's enough surviving languages to build more data? I get that we may never take Burushaski and trace it back to some distant ancestor; being that it's just Burushaski and its many dialects that survive, kinda like Basque.....

But with the IndoEuropean languages, there are so many descendants, that we can reconstruct with a fair bit of confidence ProtoIndoEuropean and at least three major dialects, with hints at how it may have existed internally at a PreProtoIndoEuropean level! Quite astonishing, but probably only possible with the volume of data that exists for that family.


Thursday, February 19, 2015

ProtoIndoEuropean and Tsezic

Was cruising the interwebs for a "next project", when I stumbled upon the wikipedia page for Tsezic. My oh my! There're some intriguing resemblances between Tsezic and the IndoEuropean languages (though the other Northeast Caucasian languages as well):

Regarding case endings

ProtoIndoEuropean
Tsezic
Khwarshi
Tsez
Hunzib
Nom.Sg
-s, -Ø
Abs. Sg.
-∅
Abs. Sg.
-∅
Abs.Sg.
-∅
Ins. Sg.
-(e)h₁
Erg. Sg.
-(j)i
Erg. Sg.
-ā
Erg. Sg.
-y
Gen. Sg.
-s,-os, -es
Gen. sg. 1
-s
Gen.Sg.1
-(e)s
Gen. Sg.
-s


Ins. Sg.
-z
GenSg.2
-(e)z


Voc. Sg.
-Ø, -ĕ
Voc. Sg.
-ju


Ins. Sg.
-d1 / -do2

Quite a neat resemblance, eh? Well, that's nothing. Not only is this mirrored pretty much acrossed Northeast Caucasian, you can expand this to ProtoUralic, and you'll find even more similarities. This isn't just limited to nominal endings, but extends to similarities between their pronominal systems as well. Likely, these features seem to have been borrowed in one direction or another. Given the degree of similarities between these obviously, otherwise unrelated languages:

PIndoEuropean
Tsezic
ProtoUralic
Khwarshi
Tsez
Hunzib
NomSg
-s, -Ø
Abs. Sg.
-∅
Abs. Sg.
-∅
Abs.Sg.
-∅
Nom.Sg.
-∅
Ins.Sg.
-(e)h₁
Erg. Sg.
-(j)i
Erg. Sg.
-ā
Erg. Sg.
-y


Gen.Sg.
-s,-(o/e)s
Gen. sg.
-s
Gen.Sg.1
-(e)s
Gen. Sg.
-s


Ins. Sg.
-z
GenSg.2
-(e)z


Voc.Sg.
-Ø, -ĕ
Voc. Sg.
-ju


Abl. Sg.
-(e)d


Ins. Sg.
-d/-do
Abl. sg.
-ta
Acc. Sg.
-m


Acc. Sg.
-m

There are also similarities with the pronominal endings, and between pronominal endings and nominal endings. These aren't dealt with here. There's also similarities between numeral endings. While ProtoIndoEuropean is primarily inflectional, it has no true means of forming new plurals, outside adding the nominative -es, many of its endings do seem to exhibit a plural -s, and a dual -h1 (which was most likely a glottal stop).

ProtoUralic had -k- in the dual, and -j-/-t in the plural.

Northeast Caucasian seems to have had some variation on a postalveolar -s- or -z- just before the case (like we see in ProtoUralic, but unlike what we see in Protoindoeuropean.

Similarities of this sort aren't uncommon between unrelated languages. Though there are alot of them in this general area, too many in fact, to just brush off the similarities. In my own view, it seems as if, alongside the prepositions of ProtoIndoEuropean, seem to have been borrowed from a common source. Or that there was alot of contact between these languages, that they became more similar with time at some point in recent prehistory.

Monday, December 29, 2014

What annoys me about encyclopedia articles

I'm aware that no article is perfect, and I've got poorly written ideas of my own. Though its frustrating running into encyclopedia and other articles on subjects, that are poorly sourced, poorly written, and reflect the writer's lack of knowledge (while pretending to know more than they do).

Looking through the Encyclopedia Britannica's article on the Baltic Languages, in the section on their developement, we find this:

"By the middle of the 1st millennium BC, the Proto-Baltic area was already sharply split into dialects. From the middle of the 1st millennium AD, the Baltic language area began to shrink considerably; at that time the greater part of Baltic territory, the eastern part, began to be inhabited by Slavs migrating from the south. The Balts there were gradually assimilated by the Slavs; complete assimilation probably occurred around the 14th century. One of these Baltic tribes, the Galindians (Goljadĭ), is mentioned in a chronicle as late as the 12th century. The protolanguage of the so-called Eastern Balts split into Lithuanian and Latvian (Latgalian) around the 7th century. The other languages of the so-called Eastern Balts became separated probably at the same time. Selonian and Semigallian could have been transitional languages between Lithuanian and Latvian. Only Curonian, which some consider to be a transitional language between East and West Baltic, might have developed somewhat earlier. Moreover, the name of the Curonians occurs in historical sources earlier (ad 853: Latin Cori) than the names of the other tribes of the so-called Eastern Balts."

Chunky paragraph aside, this is really sloppy and hard to follow. It looks like someone published their pre-published notes as the completed product.

Another problem, is that they don't state their evidence for ProtoBaltic as splitting from ProtoSlavic (assuming it did, and that its not an areal family) during the 2nd millenium BCE, nor that it was split into 2 dialects by the 1st millenium CE. I'm not saying that it wasn't, but can't you point to the evidence?

I guess this wouldn't be a problem if half the internet didn't parrot the same  wordy substance-light article, making an already obscure subject like historical linguistics, even harder to learn more about.

The way that I would have written this, would be to split it into at least three paragraphs. One that dealt with the language family as a whole, and the period before the split. Then the next paragraphs about each of the  Baltic language family groups individually.

Monday, December 15, 2014

North Picene: An Analysis and a possible interpretation of parts

Starting with the Novilara Stele, let's highlight both possible endings, stems, and affixes. Note, I'm starting from the educated guess that this is, in fact, an IndoEuropean language, although this isn't yet proven.

Suggested roots will be in black, stems/affixes in (mainly) red, and endings in blue.

The Novilara Stele
mimniś erút gaareśtadeś
rotnem úvlin partenúś
polem iśairon tet
śút tratneši krúviś
tenag trút ipiem rotneš
lútúiś θalú iśperion vúl
teś rotem teú aiten tašúr
śoter merpon kalatne
niś vilatoś paten arn
úiś baleśtenag andś et
šút iakút treten teletaú
nem polem tišú śotriś eúś
While I don't particularly think that all of these represent how you could break this down, it does demonstrate the point that, structurally, it does seem IndoEuropeanish. Also, other than -ag and -p-, all of the endings do look like stems and endings that have other IndoEuropean counterparts.
The following fragment, I will skip, due to the difficulties that would occur in analyzing it, at least with what I know of it:

1st Fragment
úpeś
mresveat

This next fragment is analyzeable:

2nd Fragment

pa śatigot
kešoteri
amdet : nk
------ k --------

Other than the suffixes -ti- and -ter- (if that's how they're divided), and endings -ot and -i, this looks noteably less indoeuropeanish than the main stele.
And finally, the last text:

3rd Fragment
tiperašθe raiup bav---
-----ipš---------------------

Counting this as indoeuropean, I've basically gone on the assumption that -a- might have been from e+Laryngeal>a. Though other possibilities exist.
As you can see, the fragments seem noteably less indoeuropean than the maintext. Whether this is due to the fragmentary nature of these short inscriptions, or due to this not being indoeuropean, is something that can be explored further.
Now that we've looked at how this could be analyzed, let's take a second look, shall we?
It seems that the longer words may be verbs.

The Novilara Stele (A closer look)
1. mimniś erút gaareśtadeś
2. rotnem úvlin partenúś
3. polem iśairon tet
4. śút tratneši krúviś
5. tenag trút ipiem rotneš
6. lútúiś θalú iśperion vúl
7. teś rotem teú aiten tašúr
8. śoter merpon kalatne
9. niś vilatoś paten arn
10. úiś baleśtenag andś et
11. šút iakút treten teletaú
12. nem polem tišú śotriś eúś


I find the end of line 2 and beginning of line 3 interesting. Last word in line 2 resembles vulgar latin "(nos) partimos ~ (nos) part(y)amos" or 1st person present plural indicative~Subjunctive verb form of partire "to depart, leave".
Line 3 starts with what appears to be the Accusative singular form of the greek word polis "city", or in this case pol-em:

2. (...) partenúś
3. polem (...)

Perhaps, this part may be translated as:
2. (...) we left
3. the city (...)

The following word is less clear in meaning, but tentatively, we can view the -on as the genitive plural ending.
Iśairon

So, we have:
"(...) we left the city of Isair (...)"

If this is a proper interpretation of this section, this doesn't mean that this is an Italic nor Greek language that we're dealing with here. These could, in fact, be derived from words from those families, if not being direct loans themselves. In much the same way as terms like "ad hoc" and deja vu" from Latin and French are left untranslated, yet, form meaningful phrases in Modern English.

Lines 9 and 10 seem to have a plural personal pronoun + Verb combination:
niś vilatoś
úiś baleśtenag

Niś appears to be in the first person plural pronoun nes (Nominative nos) in the accusative case, and úiś appears to be the 2nd person plural pronoun wes (Nominative wos) in the accusative case. The nes~nos and wes~wos coming from ProtoIndoEuropean. The only problem with this, is that they would be enclitic forms.
The verb balestenag can be interpreted as having the elements -est-en-ag in it. The ending -ag appears in multiple places, though what an IndoEuropean equivalent would be is wanting. Though the -este- ~ -est- ~ -ste- could be a realization of -st-, which may have come from the PIE suffix -skʲ-. This same cluster can be found in line one with gaarestades; which could be analyzed as gaare-sta-d-es (among other interpretations).
The above seems to have a perfect suffix -d- and a perfect/past 2nd person singular ending -es, of which I'm not sure is supposed to occur in IndoEuropean. Or, perhaps, -des is meant, which may have come from the end person plural ending -tes (or perhaps, -ates). The later, though would require -t->-d-, seems more likely.
In line 6, iśperion seems to be conjugated like the greek name hyperion, but I'm not clear on what the root isper would represent.
Soter~sotri seems to be a greek loanword "savior", which can be an epithet for gods, heros, and kings.

For a broader look, to wrap this up for now, would give the following for case endings:

Nominative or Genetive singular, or Nominative and/or Accusative Plural (possibly all of the above) -(e/i)s
Accusative Singular -(e)m
Genetive Plural -(e)n

North Picene: What remains of a 2500 year old language

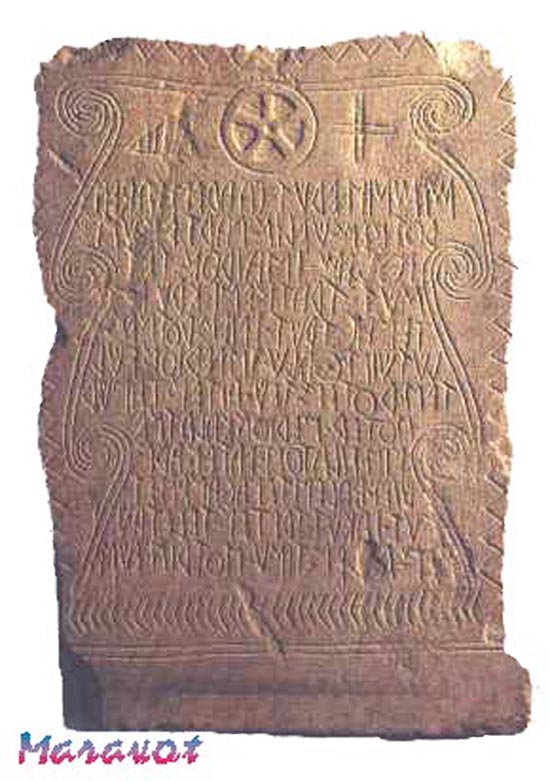
North Picene is an unclassified language from Northeastern Italy, preserved on stelai fragments from the 800-650 BCE period. A quick look at the best preserved inscription, the Novilara Stele, suggests that the language might be IndoEuropean. Other proposals have also been suggested, but this is the one we're to look at today.

The Novilara Stele (6th Century BCE)
mimniś erút gaareśtadeś
rotnem úvlin partenúś
polem iśairon tet
śút tratneši krúviś
tenag trút ipiem rotneš
lútúiś θalú iśperion vúl
teś rotem teú aiten tašúr
śoter merpon kalatne
niś vilatoś paten arn
úiś baleśtenag andś et
šút iakút treten teletaú
nem polem tišú śotriś eúś


For an image of this stele:


And according to this post in this forum:

mimniś erút gaareśtadeś
rotneš úvlin parten úś
polem iśairon tet
šút tratneši krúš
tenag trút ipiem rotneš
lútúiś θalú iśperion vúl
teś rotem teú aiten tašúr
śoter merpon kalatne
niś vilatoś paten arn
úiś baleśtenag andś et
šút lakút treten teletaú
nem polem tišú śotriś eúś

possible alternative readings:
line 1: gaariśtadeś
line 2: partenúś
line 4: krúś
line 5: rotnem
line 8: merion
line 11: mút iakút

And as for the other fragmentary texts, also found in Novilara, according to that forum post:

2nd Stele (left half of two lines)
úpeś
mresveat

The ú in line 1 might also be an L.
In line 2 ve could also be ev or ee.

3rd fragmentary text

pa śatigot
kešoteri
amdet : nk
------ k --------
The p in line 1 is uncertain.

4th fragmentary text
tiperašθe raiup bav---
-----ipš---------------------

I like how the user Arnth also added sidenotes:

"There appears to be some flexion at work: rotnem - rotneš, śoter - śotris.

Similarities to Greek words: polem - polis, śoter - soter, iśperion – esperios."

I noticed this as well, and they're (well at least some of them) transparently IndoEuropean! Though they also note how the -sv- element is also found in North Etruscan, as well as several other features also being possibly Etruscan (so it's not a done deal what language family this belongs to).

Now that we've presented the evidence of this language, let's start picking it apart, shall we?

Sunday, September 14, 2014

Is or Was ProtoIndoEuropean a Split Ergative Language?

I've heard of this theory before, but I never quite gave it much thought. It was seemingly an outdated idea first posited by

I noticed a pattern, one thats relatively easy to see if you lay it out in the form of a table. It seems like animate and inanimate case endings, at least with the nominative case, seem to correspond roughly with what one might expect from a split ergative case pattern. Animate being, or having developed from, an Ergative case; And Inanimate endings being the Absolutive form:
Nominal Endings for the Nominative, Vocative, and Accusative Cases


Animate
Inanimate/Neuter
Singular
Dual
Plural
Singular
Dual
Plural
Nominative
-s/-os
-h₁e /-oh₁e
-es
-Ø/-om
-ih₁/-oih₁
-h₂/-eh₂>-ā
Vocative
-Ø /-ĕ
-h₁e -oh₁e
-es
-Ø/-om
-ih₁/-oih₁
-h₂/-eh₂>-ā
Accusative
-m/-om
-h₁e/-oh₁e
-ns
-Ø/-om
-ih₁/-oih₁
-h₂/-eh₂>-ā
Source: http://en.wikipedia.org/wiki/Proto-Indo-European_nominals

See a pattern?

Now, there are other -h2- forms, of which use -h2- followed by case endings, which I believe could have been seperate case endings. I'm not sure if this table is accurate, its based on the wikipedia article, I was under the impression that neuter endings were seperate from the -h2- endings, which gave rise to the feminine nominal conjugation. I could be wrong, but which it derives from is irrelevant.

This pattern is also seen in Hittite, though with a different set of endings than what wikipedia has for ProtoIndoEuropean:


Animate Nouns
Neuter/Inanimate/Common Nouns
Singular
Plural
Singular
Plural
Nominative
-as
-ēs
-an
-a
Accusative
-an
-us
-an
-a

Notice, that in both instances, the Nominative and Accusative endings for the Neuter/Inanimate are identical. Also, for Animate endings, the two are not identical. Also, outside of the Nominative and Accusative cases, the Animate and Neuter/Inanimate/Common Noun endings are indistinguishable.

This on its own is nothing special, except, we also know that Hittite Neuter nouns can't function as the subject of a transitive verb, rather, their endings must be replaced by Ergative Endings:


Animate
Neuter
Singular
Plural
Singular
Plural
Nominative
-as
-ēs
-an
-a
Ergative
-as
-ēs
-anza
-antēs
Accusative
-an
-us
-an
-a

It's also known that NeoHittite slowly began to confuse Nominative and Accusative Animate plural endings, possibly another indicator of an association between the two. Then again, this easily could be related to the fact that Hittite neighbored and even had a substrate that was an Ergative language. So this need not necessarily be an archaic feature preserved in Hittite.

Its thought that the Ergative case endings for Hittite Neuter nouns originated from a derivationalized form of a suffix -ant-. I'd like to point out that its similar to the Imperfect participle, and 3rd person plural -nt- endings, which are also Active in ProtoIndoEuropean. Perhaps this is the origin of the Ergative case marker?

Active-Nominative Sing. -nt-s>-nz, -nt-es>-entes

The construction seems built upon the animate endings.

A reconstruction of the original paradigm, if ProtoIndoEuropean at some point in its history was a Split Ergative language, it might have looked something like this:

A Possible Reconstruction of ProtoIndoEuropean's Morphosyntactic Case System


Singular
Dual
Plural
Nominative
-Ø/-om
-ih₁/-oih₁
-h₂/-eh₂>-ā
Ergative
-s/-os
-h₁e /-oh₁e
-es
Accusative
-m/-om
-h₁e/-oh₁e
-ns

The beauty of this system is that, the only thing that is lost are the use of "Nominative Dual and Plural" endings to mark the Accusative in Neuter Nouns. As the Neuter paradigm is lost. Though as can be seen from -h2- reconstructions, -h2m can be reconstructed for the Accusative, so all is not really lost.
Also, the Vocative and the Nominative/Oblique, in my view, would have originally been the same case. This makes the Nominative-Vocative very similar to what we find in ProtoUralic, though I can get to the similarities between IE and U in another post. 

For more thoughts on the Ergative Case in PIE:

http://www.kortlandt.nl/publications/art049e.pdf

https://ojs.lib.byu.edu/spc/index.php/DLLS/article/viewFile/31178/29637

https://repozytorium.amu.edu.pl/jspui/bitstream/10593/7433/1/PSiCL_44_4_Bavant.pdf

I realize that there are critics of this theory, but  I don't quite think that the case is closed on Ergativity in PIE; far from it.

Tuesday, August 19, 2014

Thoughts on IndoEuropean Nominal Ablaut Patterns Part 2

Now, with different ablaut types, this apparent "stress related" vowel change, seems to be realized slightly differently. Since these ablaut patterns are highly regular, you'll see me focus primarily on the Nonnarten Acrostatic forms, as they're the easiest on the eyes to see. In reality, what I've shown can apply to pretty much all ablaut forms.


Now, regarding my original idea before the stress-related idea, I had spotted another possibility. I'd like to explore the idea, that at least in the case of the root-vowel, that the:

o-grade - Marked a sort of "default" case, including the Nominative, Vocative, and Accusative cases.

e-grade - Marked cases that were either Genetival and or Prepositional in meaning.

While not far off from my previous post, its an idea I'd like to explore further as well. It's not entirely exclusive from it either, as this system could reasonably have arisen from the previous.

Though once you get to the secondary places where you'll find vowels, such as in the stems and endings, this gets a little trickier. For instance, half the plural endings have -o- in them (Genetive, Ablative, Dative (alternatively -mus), and Ablative. Though it wouldn't necessarily contradict my hypothesis, it creates problems for my stress-related theory when it comes to certain Ablaut forms, where the ablaut vowel falls in the stem, though these differences are resolveable, it still bothers my thirst for simplicity.

As far as the verbs are concerned, I'll get to them at a later date. I want to try to not quote wikipedia twice if I can't help it. Especially since I'm less familiar with the ablaut when it comes to verbs, I won't so easily spot the error and be able to correct them. At least not at this time.

Saturday, August 16, 2014

Thoughts on IE Nominals and Ablaut

 I'm curious about a pattern I noticed with nouns, there seem to be two basic clusters that noun cases fall into; At least when it comes to their basic ablaut patterns. We'll call them Cluster A and Cluster B, and they're defined by their ablaut forms:

Cluster A: Nominative, Vocative, and Accusative
Cluster B: Instrumental, Dative, Ablative, Genetive, and Locative

I wasn't sure what I was seeing in this. I was tempted to compare it to Arabic and Akkadian's case conjugations. Which in the case of Arabic offers up Nominative -u, Accusative -a, and Possessed/Genetive -i. I'm not so sure that correlation is meaningful though, especially since I know too little of the nominal conjugations of the other AfroAsiatic languages to draw such a connection. So I set the idea to the backburner.

It was a curious pattern from a language I created, that developed when -e- became an oblique form that eventually replaced the use of -o- when Acrostatic root nouns were highly productive. Especially when I added an Ergative -a-, so the pattern was freaky similar, but was a coincidence I'd otherwise have missed. 

In all honesty, I knew from the start it was a coincidence. Though it was a curious one, and it got me thinking about it. Obsessing over the ablaut is a better term. I wanted to know its origin. What if it evolved from an earlier consonantal root system? Or maybe it was developing in that direction and stopped?  I didn't have any convincing ideas as of yet.

Though while writing this, I did think about Uralic and its stress patterns at the level of ProtoUralic, and I noticed that it followed this basic formula:
CV=Syllable, and not Consonant+Vowel specifically per se, at least here:
CV́CVCV̀CV(CV̀)(CV),etc...

Due to their geographical proximity towards one another, what if at a stage earlier than what is reconstructed for ProtoIndoEuropean, or possibly at the level of ProtoIndoEuropean itself, it had this same basic pattern? Perhaps, like the above, its a pattern that doesn't really exist, but has seemed to have appeared by coincidence. Though I think its an interesting idea to explore nonetheless.

What I'm thinking is, what if -o- became -e- when preceeded by an adposition of some sort? As if at one point, adpositions influenced the way the noun they modified was pronounced. In the same way that the noun that is modified by the indefinite article in Modern English, influences the way the indefinite article is pronounced:

The indefinite article, when preceeding a Noun that starts with a vowel or consonant, becomes:
Vowel: an
Consonant: a

In other words, perhaps:

Singular Acrostatic Root Noun "night"

sing.nom.nókʷt-s
voc.nókʷt
acc.nókʷt-m̥
inst.kóm nékʷt-(e)h₁
dat.dó nékʷt-ey
abl.h₂ét nékʷt-s
gen.h₂ét nékʷt-s
loc.ʔén nékʷt-(i)
dualnom.-voc.-acc. nókʷt-h₁e
plur.n.-v.nókʷt-es
acc.nókʷt-n̥s
inst.kóm nékʷt-bʰi
dat.-abl.dó nékʷt-m̥os
gen.ʔén nékʷt-oHom
loc.ʔén nékʷt-su

What I immediately liked about this idea, was that I really didn't have to change much. Though I did have to suppose that, as a rule, any noun in Case Cluster B, was required to be preceeded by an adposition, or some sort of particle or prefix. While I'd like to see someone with actual university-level credentials on historical linguistics analyze this (not just my armchair amateurish theorization), I would like to note some potential evidence and flaws for this idea:

In the case of the word "fatherless":

Ablaut grade PIE (reconstruction) Greek (Greek transliterated) Translation
e-grade or full grade *ph2-tér-m̥ πα-τέρ-α pa-tér-a "father" (noun, accusative)
lengthened e-grade *ph2-tḗr πα-τήρ pa-tḗr "father" (noun, nominative)
zero-grade *ph2-tr-és πα-τρ-ός pa-tr-ós "father's" (noun, genitive)
o-grade *n̥-péh2-tor-m̥ ἀ-πά-τορ-α a-pá-tor-a "fatherless" (adjective, accusative)
lengthened o-grade *n̥-péh2-tōr ἀ-πά-τωρ a-pá-tōr "fatherless" (adjective, nominative)

Now, I'm not sure if the vowel patterns have more to do with having a prefix attached or if its something that happens with the inclusion of an adjective, I'd like to hear someone in the field's take on it. In the meantime, I'll be researching this further. (No, wikipedia isn't my main source for PIE, its simply convenient for copying and pasting.)

It appears like the inclusion of a prefix or particle before the noun, is what changed the vowels within the Noun itself.

However, there is a slight problem with this, at least in the case of the negative prefix n-, It would have been predicted that the prefix would get the stress, not the root. Or perhaps, like with ʔeme>me after the loss of the laryngeal, a prior particle ʔene>ne~n was similarly reduced?


As you can see below in the chart taken from wikipedia, suffixes do sometimes have influence upon how vowel patterns are realized, or so it seems. It does seem to appear to be stress-related in nature. At least from what I can tell. This doesn't deal so much with my theory, and would necessarily be knowledged gleaned before my hypothesis came into existence, so it can't really be used as evidence of any sort:

Taken from Wikipedia:
 http://en.wikipedia.org/wiki/Proto-Indo-European_nominals


acrostatic root noun acrostatic lengthened root noun amphikinetic (?) root noun hysterokinetic r-stem amphikinetic n-stem hysterokinetic n-stem
gloss night (f.) moon (m.) foot (m.) father (m.) lake (m.) bull (m.) (< "ox")
sing. nom. *nókʷts *mḗh₁n̥s *pṓds *ph₂tḗr *léymō *uksḗn
voc. *nókʷt *mḗh₁n̥s *pód *ph₂tér *léymon *úksen
acc. *nókʷtm̥ *mḗh₁n̥sm̥ *pódm̥ *ph₂térm̥ *léymonm̥ *uksénm̥
inst. *nékʷt(e)h₁ *méh₁n̥s(e)h₁ *pedéh₁ *ph₂tr̥éh₁ *limnéh₁ *uksn̥éh₁
dat. *nékʷtey *méh₁n̥sey *pedéy *ph₂tr̥éy *limnéy *uksn̥éy
abl. *nékʷts *méh₁n̥sos *pedés *ph₂tr̥és *limnés *uksn̥és
gen. *nékʷts *méh₁n̥sos *pedés *ph₂tr̥és *limnés *uksn̥és
loc. *nékʷt(i) *méh₁n̥s(i) *péd(i) *ph₂tér(i) *limén(i) *uksén(i)
dual nom.-voc.-acc. *nókʷth₁e *mḗh₁n̥sh₁e *pódh₁e *ph₂térh₁e *léymonh₁e *uksénh₁e
plur. n.-v. *nókʷtes *mḗh₁n̥ses *pódes *ph₂téres *léymones *uksénes
acc. *nókʷtn̥s *mḗh₁n̥sn̥s *pódn̥s *ph₂térn̥s *léymonn̥s *uksénn̥s
inst. *nékʷtbʰi *méh₁n̥sbʰi *pedbʰí *ph₂tr̥bʰí *limn̥bʰí *uksn̥bʰí
dat.-abl. *nékʷtm̥os *méh₁n̥smos *pedmós *ph₂tr̥mós *limn̥mós *uksn̥mós
gen. *nékʷtoHom *méh₁n̥soHom *pedóHom *ph₂tr̥óHom *limn̥óHom *uksn̥óHom
loc. *nékʷtsu *méh₁n̥su *pedsú *ph₂tr̥sú *limn̥sú *uksn̥sú


proterokinetic neuter r/n-stem amphikinetic collective neuter r/n-stem amphikinetic m-stem proterokinetic ti-stem proterokinetic tu-stem proterokinetic neuter u-stem
gloss water (n.) water(s) (n.) earth (f.) thought (f.) taste (m.) tree (n.)
sing. nom. *wódr̥ *wédōr *dʰéǵʰōm *méntis *ǵéwstus *dóru
voc. *wódr̥ *wédōr *dʰéǵʰom *ménti *ǵéwstu *dóru
acc. *wódr̥ *wédōr *dʰéǵʰōm *méntim *ǵéwstum *dóru
inst. *udénh₁ *udnéh₁ *ǵʰméh₁ *mn̥tíh₁ *ǵustúh₁ *drúh₁
dat. *udéney *udnéy *ǵʰméy *mn̥téyey *ǵustéwey *dréwey
abl. *udéns *udnés *ǵʰmés *mn̥téys *ǵustéws *dréws
gen. *udéns *udnés *ǵʰmés *mn̥téys *ǵustéws *dréws
loc. *udén(i) *udén(i) *ǵʰdʰsém(i) *mn̥téy (-ēy) *ǵustéw(i) *dréw(i)
dual nom.-voc.-acc.


*méntih₁ *ǵéwstuh₁ *dórwih₁
plur. n.-v.


*ménteyes *ǵéwstewes *dóruh₂
acc.


*méntins *ǵéwstuns *dóruh₂
inst.


*mn̥tíbʰi *ǵustúbʰi *drúbʰi
dat.-abl.


*mn̥tímos *ǵustúmos *drúmos
gen.


*mn̥téyoHom *ǵustéwoHom *dréwoHom
loc.


*mn̥tísu *ǵustúsu *drúsu


neuter s-stem proterokinetic h₂-stem hysterokinetic h₂-stem eh₂-stem (ā-stem) o-stem neuter o-stem
gloss cloud (n.) woman (f.) (> "queen") tongue (f.) grain (f.) nest (m.) work (n.)
sing. nom. *nébʰos *gʷḗn *dn̥ǵʰwéh₂s *dʰoHnéh₂ *nisdós *wérǵom
voc. *nébʰos *gʷḗn *dń̥ǵʰweh₂ *dʰoHn[á] *nisdé *wérǵom
acc. *nébʰos *gʷénh₂m̥ *dn̥ǵʰwéh₂m (-ām) *dʰoHnéh₂m (-ā́m) *nisdóm *wérǵom
inst. *nébʰes(e)h₁ *gʷnéh₂(e)h₁ *dn̥ǵʰuh₂éh₁ *dʰoHnéh₂(e)h₁ *nisdóh₁ *wérǵoh₁
dat. *nébʰesey *gʷnéh₂ey *dn̥ǵʰuh₂éy *dʰoHnéh₂ey *nisdóey *wérǵoey
abl. *nébʰesos *gʷnéh₂s *dn̥ǵʰuh₂és *dʰoHnéh₂s *nisdéad *wérǵead
gen. *nébʰesos *gʷnéh₂s *dn̥ǵʰuh₂és *dʰoHnéh₂s *nisdósyo *wérǵosyo
loc. *nébʰes(i) *gʷnéh₂(i) *dn̥ǵʰwéh₂(i) *dʰoHnéh₂(i) *nisdéy *wérǵey
dual nom.-voc.-acc. *nébʰesih₁ *gʷénh₂h₁e *dn̥ǵʰwéh₂h₁e  ? *nisdóh₁ *wérǵoy(h₁)
plur. n.-v. *nébʰōs *gʷénh₂es *dn̥ǵʰwéh₂es *dʰoHnéh₂es *nisdóes *wérǵeh₂
acc. *nébʰōs *gʷénh₂n̥s *dn̥ǵʰwéh₂ns (-ās) *dʰoHnéh₂ns (-ās) *nisdóns *wérǵeh₂
inst. *nébʰesbʰi *gʷnéh₂bʰi *dn̥ǵʰuh₂bʰí *dʰoHnéh₂bʰi *nisdṓys *wérǵōys
dat.-abl. *nébʰesmos *gʷnéh₂mos *dn̥ǵʰuh₂mós *dʰoHnéh₂mos *nisdó(y)mos *wérǵo(y)mos
gen. *nébʰesoHom *gʷnéh₂oHom *dn̥ǵʰuh₂óHom *dʰoHnéh₂oHom *nisdóoHom *wérǵooHom
loc. *nébʰesu *gʷnéh₂su *dn̥ǵʰuh₂sú *dʰoHnéh₂su *nisdóysu *wérǵoysu

Athematic Thematic
acrostatic root noun hysterokinetic r-stem proterokinetic ti-stem proterokinetic neuter u-stem eh₂-stem (ā-stem) o-stem neuter o-stem
PIE Post-PIE1
gloss night (f.) father (m.) thought (f.) tree (n.) grain (f.) nest (m.) work (n.)
sing. nom. *nókʷt-s *ph₂t-ḗr *mént-i-s *dór-u *dʰoHn-éh₂ *dʰō̬n-ā̬́ *nisd-ó-s *wérǵ-o-m
voc. *nókʷt *ph₂t-ér *mént-i *dʰoHn-[á]2 *dʰō̬n-á *nisd-é
acc. *nókʷt-m̥ *ph₂t-ér-m̥ *mént-i-m *dʰoHn-éh₂-m (-ā́-m) *dʰō̬n-ā̬́-m *nisd-ó-m
inst. *nékʷt-(e)h₁ *ph₂t-r̥-éh₁ *mn̥t-í-h₁ *dr-ú-h₁ *dʰoHn-éh₂-(e)h₁ *dʰō̬n-ā̬́? *nisd-ó-h₁ *wérǵ-o-h₁
dat. *nékʷt-ey *ph₂t-r̥-éy *mn̥t-éy-ey *dr-éw-ey *dʰoHn-éh₂-ey *dʰō̬n-ā̬́-y *nisd-ó-ey *wérǵ-o-ey
abl. *nékʷt-s *ph₂t-r̥-és *mn̥t-éy-s *dr-éw-s *dʰoHn-éh₂-s *dʰō̬n-ā̬́-s *nisd-é-ad *wérǵ-e-ad
gen. *nékʷt-s *ph₂t-r̥-és *mn̥t-éy-s *dr-éw-s *dʰoHn-éh₂-s *dʰō̬n-ā̬́-s *nisd-ó-syo *wérǵ-o-syo
loc. *nékʷt-(i) *ph₂t-ér-(i) *mn̥t-éy (-ēy) *dr-éw-(i) *dʰoHn-éh₂-(i) *dʰō̬n-á̬-y *nisd-é-y *wérǵ-e-y
dual nom.-voc.-acc. *nókʷt-h₁e *ph₂t-ér-h₁e *mént-i-h₁ *dór-w-ih₁  ?  ? *nisd-ó-h₁ *wérǵ-o-y(h₁)
plur. n.-v. *nókʷt-es *ph₂t-ér-es *mént-ey-es *dór-u-h₂ *dʰoHn-éh₂-es *dʰō̬n-ā̬́-s *nisd-ó-es *wérǵ-e-h₂
acc. *nókʷt-n̥s *ph₂t-ér-n̥s *mént-i-ns *dʰoHn-éh₂-ns (-ās) *dʰō̬n-ā̬́-s *nisd-ó-ns
inst. *nékʷt-bʰi *ph₂t-r̥-bʰí *mn̥t-í-bʰi *dr-ú-bʰi *dʰoHn-éh₂-bʰi *dʰō̬n-ā̬́-bʰi *nisd-ṓ-ys *wérǵ-ō-ys
dat.-abl. *nékʷt-m̥os *ph₂t-r̥-mós *mn̥t-í-mos *dr-ú-mos *dʰoHn-éh₂-mos *dʰō̬n-ā̬́-mos *nisd-ó-(y)mos *wérǵ-o-(y)mos
gen. *nékʷt-oHom *ph₂t-r̥-óHom *mn̥t-éy-oHom *dr-éw-oHom *dʰoHn-éh₂-oHom *dʰō̬n-á̬-ō̬m *nisd-ó-oHom *wérǵ-o-oHom
loc. *nékʷt-su *ph₂t-r̥-sú *mn̥t-í-su *dr-ú-su *dʰoHn-éh₂-su *dʰō̬n-ā̬́-su *nisd-ó-ysu *wérǵ-o-ysu